Create 100% Royalty-free AI Videos & Images for any commercial use
Create & Discover Stunning AI Videos & Images
Explore thousands of AI video and image prompts for AI Video Generator. Browse curated examples, gather creative inspiration, and generate professional-quality content with our AI-powered tools and prompt library.
Powerful AI Models at Your Fingertips
Choose from industry-leading AI models for image and video generation. Each model offers unique capabilities to bring your creative vision to life.
Veo 3.1
Google DeepMind’s upgraded AI video model for realistic motion generation, extended clip duration, multi-image reference control, and synchronized audio output in native 1080p.
Gemini Omni Video
Gemini Omni is Google’s released multimodal creation model built to create from different kinds of input, starting with video. Gemini Omni Flash is the first model in the Omni family, supporting practical video generation and editing workflows such as natural language edits, reference-based creation, scene transformation, and coherent visual storytelling.

Nano Banana 2
Meet Nano Banana 2, Google’s Gemini 3.1 Flash Image model, now available via Kie AI API. Built for developers, it combines lightning-fast speed with Pro-level quality, accurate text rendering, strong character consistency, and scalable image generation and editing workflows.

Nano Banana Pro
Google DeepMind’s Nano Banana Pro delivers sharper 2K imagery, intelligent 4K scaling, improved text rendering, and enhanced character consistency—offering a major leap in visual quality for creative and API-driven workflows.

Flux.2 Pro
Flux 2 is Black Forest Labs’ advanced image generation model that delivers photoreal detail, strong multi-reference consistency, and accurate text rendering with flexible control.

Z-Image
Z-Image is Tongyi-MAI’s efficient image generation model that delivers photorealistic output, fast Turbo performance, and accurate bilingual text rendering with strong semantic understanding.

GPT Image 2
GPT Image 2 is OpenAI’s next-gen image model built for stronger photorealism, cleaner image editing, sharper text rendering, and more polished product photography. Designed for more advanced visual workflows, it pushes image generation beyond basic text-to-image output and into higher-quality creative, commercial, and design-ready use cases.

GPT Image 1.5
GPT Image 1.5 is OpenAI’s flagship image generation model for high-quality image creation and precise image editing, with strong instruction following and improved text rendering.

Seedream 5.0 Lite
Seedream 5.0 Lite is a unified multimodal image generation model by ByteDance, designed for multimodal reasoning, deep understanding, and controllable visual creation. It supports text-to-image and image editing workflows with improved consistency and real-time knowledge integration.

Seedream 4.5
Seedream 4.5 is Bytedance’s refined image model for 4K generation, precise editing, and consistent multi-image output.
Seedance 2.0
Seedance 2.0 on KIE is a multimodal Al video model by ByteDance, optimized for fast and realistic video generation. It supports high-quality virtual human video creation with strong multi-shot consistency, enabling more lifelike and cinematic outputs across scenes.
Seedance 1.5 Pro
Seedance 1.5 Pro is ByteDance’s audio-video generation model that creates cinema-quality video, synchronized audio, and multilingual dialogue with cinematic camera control.
Kling 3.0
Kling 3.0 is Kling AI’s video generation model that creates videos from text and images, supports multi-shot storytelling, and produces native audio with cinematic control up to 15 seconds.
kling 3.0 - Motion Control
Kling Motion Control 3.0 is Kuaishou Kling’s AI video motion model that transfers movement from reference videos to character images while preserving facial identity, expressions, and realistic motion dynamics.
Kling 2.6
Kling 2.6 is Kling AI’s audio-visual generation model that produces synchronized video, speech, ambient sound, and sound effects from text or image inputs.
kling 2.6 - Motion Control
Developed by KuaiShou, Kling AI 2.6 Motion Control API is a performance-driven image-to-video model that transfers real human motion, gestures, and expressions from reference video to character images with stable timing and realism.

Wan 2.7 Image
Wan2.7-Image is Alibaba’s unified image model family for generation and editing, supporting text-to-image, image editing, advanced text rendering, multi-image workflows, 2K output in its standard variant, and 4K text-to-image in its Pro variant.

Wan 2.7 Video
Wan 2.7 Video API is Alibaba Tongyi Lab's AI video suite, covering four generation modes — Text-to-Video, Image-to-Video, Reference-to-Video, and Video Edit. It supports full-modality input (text, image, video, audio) and outputs 720P–1080P video. Access all four modes through a single API on Kie.ai.
Wan 2.6
Wan 2.6 is Alibaba’s latest AI video model, offering affordable multi-shot 1080p generation with stable characters and synchronized native audio. Through the Wan 2.6 API—including T2V, I2V, and reference-guided modes—you can create up to 15-second cinematic videos with improved motion logic, consistent visuals, and production-ready quality.
MiniMax H3
MiniMax H3, also known as Hailuo 03, unifies text, image, video, and audio for 2K video generation, multimodal referencing, native stereo sound, motion transfer, and precise editing.
Hailuo 2.3
Hailuo 2.3 is MiniMax’s high-fidelity AI video generation model designed to create realistic motion, expressive characters, and cinematic visuals. It supports both text-to-video and image-to-video, handling complex movements, lighting changes, and detailed facial expressions with stability and consistency.
Grok Imagine
Grok Imagine is xAI’s multimodal image and video generation model that converts text or images into short visual outputs with coherent motion and synchronized audio.
Video Prompts
Discover high-quality AI video prompts created with expertly crafted AI video prompts
From sun-ripened mango to velvety gelato, watch every luscious swirl and frosty detail come alive in ten seconds.
Duration: 10 seconds
A locked-off shot captures one continuous curl of wallpaper, its edge crackling and flaking. Local render, 15 seconds.
Duration: 15 seconds
A colossal arm in red plucks a miniature man from a glossy wet street in this surreal forced-perspective VFX shot.
Duration: 10 seconds
A shopper's touch triggers a chain-reaction avalanche of jars and golden liquid across the dairy aisle on fixed CCTV.
Duration: 11 seconds
She looks up in awe as emerald aurora dances above a snowy Jeongseon lake. A quiet, realistic winter escape.
Duration: 30 seconds
In a cracked desert highway, a lone sentinel faces colossal mechs, her violet powers erupting in a storm of deflected bolts and imploding robots.
Duration: 28 seconds
Image Prompts
Discover high-quality AI image prompts created with expertly crafted AI image prompts
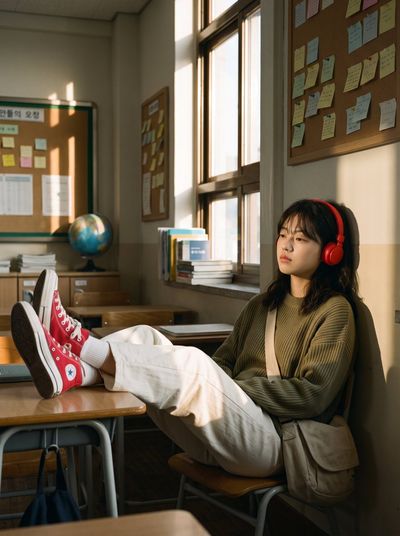
Teenage girl in sunlit classroom with red headphones and sneakers
A cinematic medium shot of a girl leaning back in a sunlit classroom, red headphones on, lost in thought as golden hour light casts dramatic shadows.
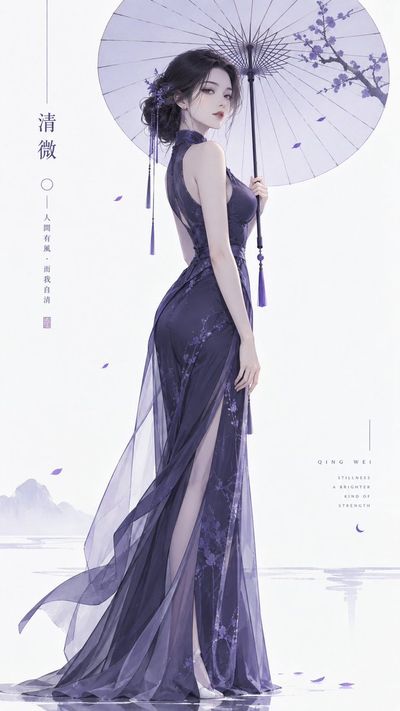
Elegant Eastern Woman Holds Minimal Paper Umbrella in Violet Light
A poised adult Asian woman stands with a simple paper umbrella, her silhouette defined by deep violet and ink-blue tones against a clean white background.
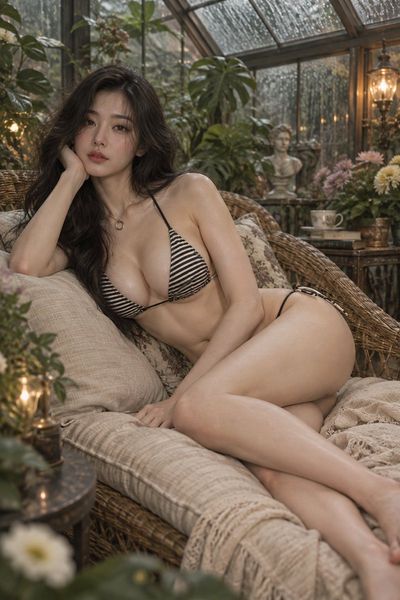
Elegant Woman Lounges in Sunlit Vintage Glass Greenhouse with Striped Bikini
A stunning 23-year-old Asian beauty reclines on a rattan chaise in a vintage glass greenhouse, wearing a black and ivory striped bikini, surrounded by lush greenery and soft rain.
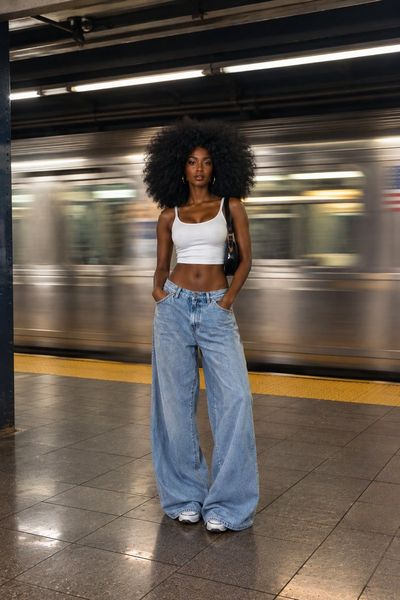
Confident Black Woman Stands Firm as Subway Train Blurs Behind Her
A high-fashion editorial portrait of a woman with a full afro, calm and sharp, while a subway train streaks with motion blur in the background.
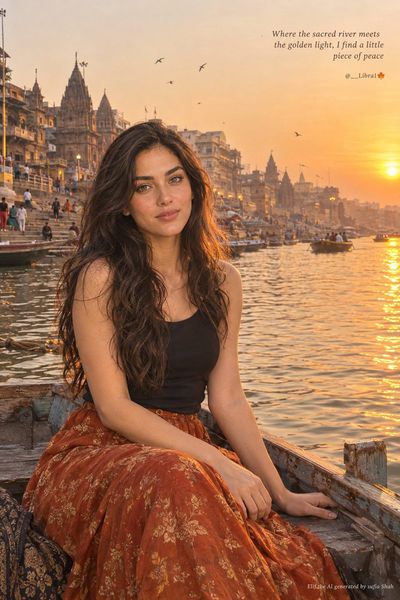
Elif Sits in Wooden Boat on Ganges at Golden Hour
Warm golden-hour travel photograph of Elif in a traditional wooden boat on the Ganges, Varanasi ghats behind her, natural and authentic.
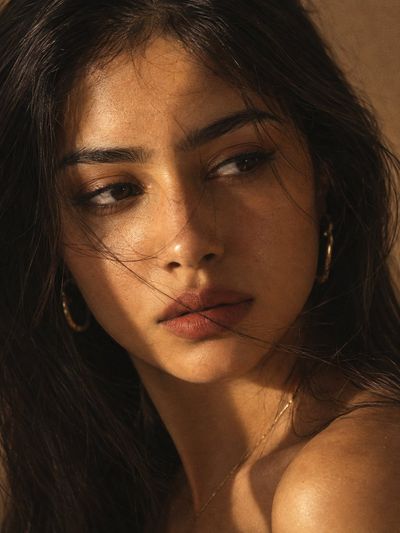
Golden Sunlight Graces a Woman's Face With Tangled Strands
A cinematic close-up of a woman's face, warm amber light carving deep shadows while loose hair strands cross her cheek and lips, evoking quiet contemplation.
All-in-One AI Image & Video Generator
Access all leading AI models in one platform. Create stunning images and videos with Veo 3.1, Wan 2.6, Sora 2 Pro, Kling 2.6, Seedance 1.5 Pro, Flux AI, Nano Banana, and more—no multiple subscriptions needed.

Trusted by Creators Worldwide
See what our users are saying
"PromptGather saved me 10 hours per week on video creation. The quality is amazing and the interface is so easy to use!"
Sarah Chen
Content Creator
"Best AI video platform I've used. The variety of models means I can always find the perfect style for my projects."
Michael Johnson
Marketing Director
"The extensive prompt library has been incredibly helpful for my work. Having so many reference examples saves me tons of time."
Emily Park
Freelance Designer
Frequently Asked Questions
Everything you need to know about AI video and image prompts